Kaufland Scraper
Kaufland's marketplace has an API, but it is built for the seller looking at their own account, not for anyone trying to read what competitors are charging. The AI scraper reads the public offer page instead, turns it into columns you define, and runs on a schedule.
- kaufland.de
- kaufland.at
- kaufland.cz
- kaufland.sk
- kaufland.pl
How to scrape Kaufland.de
Kaufland Global Marketplace, the platform that absorbed real.de, is now one of the largest third-party marketplaces in German-speaking Europe, and it is where a lot of DACH sellers quietly lose the buy box without noticing. Its programmatic access is a seller API: it authenticates as you, and it answers questions about your own listings, orders and stock. It does not exist to tell you what the seller sitting above you is charging today. There is no public read API for competitor offers, and Scrapewise does not carry a dedicated Kaufland endpoint either. What works is the offer page itself. You paste Kaufland product URLs into the AI scraper, declare the columns you want, and set a daily schedule. Every run comes back over REST, CSV or Excel, and you pay per page from a prepaid wallet.
What the AI scraper does with a Kaufland link
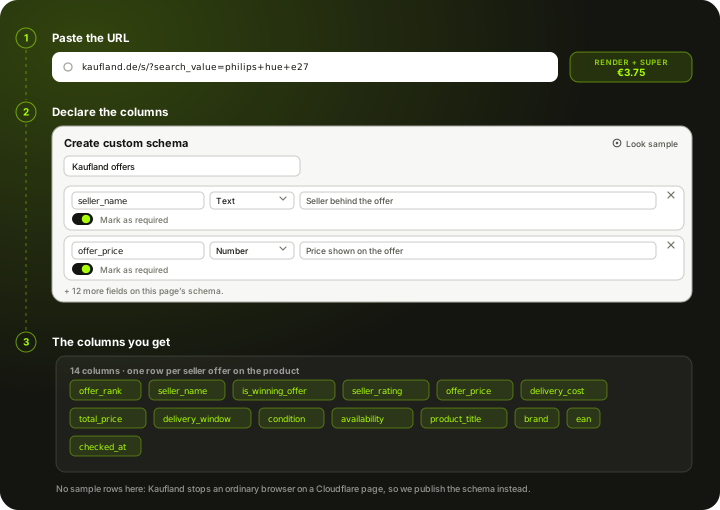
Three steps, same as any other site. Nothing about Kaufland is pre-built, which is why it reaches a marketplace no data vendor ships an endpoint for.
Paste the link
A product page, a seller's offer list, or a category URL with the filters already applied. Kaufland runs separate country sites and the scraper works from the URL you hand it, so a .de and a .cz page are simply two different inputs rather than two integrations.
You declare the columns
A Kaufland pricing job usually wants the winning offer price, delivery cost, the seller holding it, the other sellers on the same product and their prices, plus condition and stock wording. You name those fields yourself in a Custom Schema, or start from the ready Product List schema and add to it. The AI fills your fields from the page after JavaScript has run rather than from a saved selector.
Schedule it and take the data out
Run it once or daily. Pull each run by REST API or download it as CSV or Excel. The columns stay the same between runs, so a Kaufland table and an Amazon table can share the same downstream pipeline.
Set it up once. The data keeps coming.
Save your search once and it runs by itself. Every run lands in your own Scrapewise database, and you pick how to read it.
Set it up once
Add your ASINs, keywords, places or apps to a scraper in the web app. New accounts get 5 free requests.
Runs on your schedule
Pick daily, weekly on the days you choose, every few days, or the first or last day of the month. Scheduled runs start at night, European time. Need it more often? Start runs from your own code.
Saved in your database
Each run adds dated rows, so this week sits next to last week. Rows are kept for 90 days.
Use it your way
Open the table in the web app and download the latest run as an Excel file. Ask your own AI assistant about it. Or pull the rows into your code with an API key.
Ask your AI assistant about your own data
Connect Claude Desktop or Claude Code with a read-only key. The assistant reads the rows you've already collected, at no extra cost on Scrapewise. With a full-access key it can start a run for you too.
- Which of my ASINs lost the Buy Box this week?
- Which competitor cut prices the most since Monday?
- Show the keywords where I dropped out of the top 10.
What you send and what you get
You send a link and a column list. Which sellers are on the product, what they charge and who is winning all come from the page, so there is nothing else to configure.
- Link to a Kaufland product pagerequired
Open the offer page in your browser and copy the address. Any Kaufland country site works the same way.
https://www.kaufland.de/product/{product-id}/ - Your column listrequired
Start from the ready Product List schema or name your own fields in a Custom Schema. The AI fills the fields you declared.
Custom Schema, 14 fields - How often it runsoptional
- On demand
- Daily
- Weekly
- Monthly
Daily is the fastest cadence available. It is enough to see the winning offer change hands.
One row per seller offer on the product, 14 columns each
- offer_rank
- seller_name
- is_winning_offer
- seller_rating
- offer_price
- delivery_cost
- total_price
- delivery_window
- condition
- availability
- product_title
- brand
- +2 more, see all columns
REST API, CSV or Excel. The column set stays the same between runs, so a Kaufland table and an Amazon table share one pipeline.
The columns a Kaufland run gives you
We are not going to print a table of invented seller offers and call it real output. Kaufland sits behind a challenge that an ordinary browser does not clear, so a run has to go through the residential tier. This is the column list you declare before the run, and the column list every run comes back with.
offer_rankPosition of the offer on the page, winning offer firstseller_nameMerchant behind this offeris_winning_offerWhether this seller currently holds the winning positionseller_ratingSeller rating, when Kaufland displays oneoffer_priceHeadline price, before deliverydelivery_costDelivery cost as the page states ittotal_priceOffer price plus deliverydelivery_windowDelivery estimate shown with the offerconditionCondition wording on the offeravailabilityStock wording on the offer rowproduct_titleProduct title as Kaufland writes itbrandBrand shown on the producteanEAN, only when the page prints itchecked_atWhen this run collected the page (UTC)The columns are yours, not ours. Add, rename or drop any of them in a Custom Schema and every future run returns exactly your set.
What a Kaufland page costs
Pay-as-you-go from your wallet. No plan, no monthly fee, no seat count.
Measured on 24 September 2026, not assumed. A plain fetch of a Kaufland search URL is refused, and loading the same URL in a real browser stopped on a Cloudflare interstitial rather than the results. A browser alone is not enough here, so budget for a rendered page coming out of a residential exit.
300 Kaufland product pages checked once a day for a month is 9,000 pages.
about EUR 33.75 for the month at this tier
You are charged for the tier a run actually used, not the tier it was expected to need, and your balance never expires.
See the full price list →What this page is not promising
We would rather say this here than in a support ticket.
No dedicated Kaufland endpoint
There is no Kaufland data API in our catalogue and no pre-built Kaufland schema. The AI scraper reads the page you point it at, and that is the whole mechanism.
No seller-account data
Anything that lives behind the Kaufland seller login, your orders, your stock, your own buy box statistics, is not accessible to a scraper reading public pages. Kaufland's seller API is the tool for that.
No guaranteed delivery
Automated traffic gets challenged. We escalate to higher tiers, but we cannot promise every Kaufland page returns data on every run.
Daily, not real time
Daily is the fastest schedule. There is no real-time feed, no per-minute polling and no price-drop alerting.
No price-history database
We store nothing about Kaufland prices on our side. A price curve is something you build by scheduling the scraper, starting from the day you switch it on.
No SKU matching included
You get Kaufland's rows as Kaufland presents them. Mapping them to your own catalogue is a separate job, and so is repricing. We are also not lawyers, so check Kaufland's terms before you run anything.
Typical fields the AI scraper extracts from a Kaufland page
A starting point, not a fixed schema. What comes back is whatever the page actually shows on the day of the run.
Price and delivery
Kaufland shows a winning offer with other sellers underneath it. Both halves matter: one is what a shopper sees, the other is how much room there is beneath it.
- Winning offer price
- Delivery cost and delivery window
- Total delivered price
- Prices of the other sellers on the same product
- Strikethrough or reference price, when shown
Sellers on the offer
The part a brand cares about. Kaufland is a marketplace, so one product page can carry a whole roster of merchants.
- Seller name for each offer
- Which seller currently holds the winning position
- Seller rating, when displayed
- Fulfilment and shipping origin wording
- Stock and availability text
Product identity
What you match your own catalogue against. Kaufland prints identifiers more often than a comparison site does, but not on every listing.
- Product title
- Brand
- EAN, when the page prints it
- Category breadcrumb
- Rating and review count
- Product image URL
The column list is one you write: name each field, give it a type and a line telling the AI what to look for. The schema belongs to your account, so a Kaufland field set can be pointed at another marketplace without rebuilding it. How Custom Schema works →
What it cannot give you The scraper cannot invent a field the page does not render. EAN and other identifiers come back only when Kaufland prints them on the listing you scraped, and on plenty of listings it does not. Historical prices are not shown on the page and are not stored on our side, so a price curve has to be built by running the scraper on a schedule. Seller-only figures such as your own buy box share or order volume live behind the seller login and are out of reach.
What people use Kaufland data for
Watching the winning offer on your own products
If you sell on Kaufland, the question that decides your week is whether you are holding the winning position and by how little. Scraping the offer block daily answers it for every SKU at once, instead of one tab at a time.
Seeing who else is listing your SKU
For brands, the seller list on a Kaufland offer is a roster of every merchant carrying your product on the platform, including the ones you never appointed. That is the raw material for MAP and channel enforcement.
Pricing a launch onto the marketplace
Before you list, scraping the category tells you what the existing offers charge, what they charge for delivery, and how thin the spread already is. That is a cheaper way to find out than listing and watching nothing sell.
Cross-marketplace price consistency in DACH
The same SKU often sits at a different price on Kaufland than on Amazon or a comparison site. Pulling them into one table exposes both the competitor gap and the inconsistency your own channel is creating.
Feeding your own repricing rules
The export is a normal REST API or CSV, so it drops into whatever repricing logic you already run. Scrapewise supplies the observation; your rules decide what to do with it.
Assortment and gap analysis
Scraping a category shows which products are well served and which have one lazy seller charging whatever they like. That is where a new listing has room.
What makes Kaufland harder than an ordinary storefront
Not the hardest site on this hub, but the marketplace structure catches people out.
Access
- Plain HTTP requests get an incomplete page, because the offer block is not in the initial HTML
- A Cloudflare interstitial stops an ordinary browser, so runs have to go out rendered through a residential exit
- Success is high but not guaranteed; a page that refuses on one run often comes back on the next
Page structure
- The winning offer is displayed prominently and the other sellers sit behind a separate block that has to be opened
- Variants such as size and colour are separate offers, so one product family spans several URLs
- Listing quality varies by seller, so the same attribute is present on one offer and missing on the next
Country sites
- kaufland.de, .at, .cz, .sk and .pl are separate storefronts with separate seller sets
- The same product carries different offers and different prices per country
- Currency differs outside the eurozone and has to be normalised before you compare
Scheduling and delivery
- Daily is the fastest cadence, which matches how often marketplace prices meaningfully move
- Every run is retrievable by REST API, or downloadable as CSV or Excel
- Columns stay stable between runs, so downstream jobs do not need to re-map fields
Kaufland scraping — questions
What people ask before pointing the scraper at Kaufland.
No. Kaufland's marketplace API is a seller API: it authenticates as your seller account and answers questions about your own listings, orders and stock. There is no public read API that returns what other merchants are charging, which is why competitor work on Kaufland comes off the public page.
Ready to pull Kaufland.de data into your stack?
Start free — or talk to our team about your exact fields, refresh cadence and volume.