
Zappos Scraper
We do not have a dedicated Zappos data API. What we do have is an AI scraper that reads a zappos.com page you point it at, turns it into the columns you asked for and hands them back by REST, CSV or Excel — on a schedule, priced per page.
- zappos.com
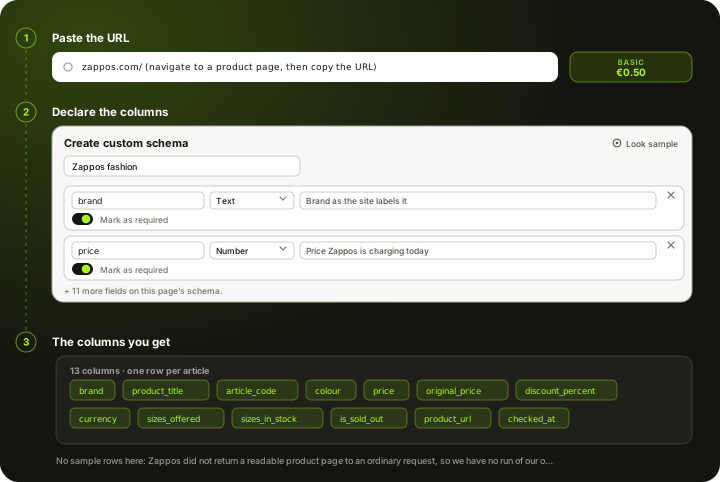
How to scrape Zappos
Zappos does run a developer portal at {'url': 'https://www.zappos.com/', 'status': 200, 'signals': ['clientid', 'endpoint', 'sandbox']}. It is built for partners and sellers rather than for someone who wants to read prices, so the access you can get through it is not the access most people arrive here looking for. Zappos prices footwear at the size level, which makes it the clearest public example of size-run pricing in US retail. The way to get the data is to read the page the way a customer sees it: point the AI scraper at a zappos.com URL, declare the columns you want in plain English, and schedule it. In fashion the shelf price is almost beside the point. What moves the market is when an article goes on markdown, how deep, and which sizes are still available when it does.
What the AI scraper does with a zappos.com link
The same three steps as any other page you point it at. Nothing about Zappos is pre-built, which is exactly why it works on pages nobody wrote a connector for.
Paste the link
Give it a zappos.com product or listing URL. Market, currency and assortment all come from the page itself, so there is no region setting to get wrong — the URL decides.
Declare the columns
Name each field, give it a type and write a line telling the AI what to look for. “brand” and “product_title” are the two most people start with. The schema is yours and you can change it between runs.
Schedule it and collect
Run it hourly, daily or on demand. Every run returns the same columns in the same order with a timestamp on each row, so the history builds itself.
Set it up once. The data keeps coming.
Save your search once and it runs by itself. Every run lands in your own Scrapewise database, and you pick how to read it.
Set it up once
Add your ASINs, keywords, places or apps to a scraper in the web app. New accounts get 5 free requests.
Runs on your schedule
Pick daily, weekly on the days you choose, every few days, or the first or last day of the month. Scheduled runs start at night, European time. Need it more often? Start runs from your own code.
Saved in your database
Each run adds dated rows, so this week sits next to last week. Rows are kept for 90 days.
Use it your way
Open the table in the web app and download the latest run as an Excel file. Ask your own AI assistant about it. Or pull the rows into your code with an API key.
Ask your AI assistant about your own data
Connect Claude Desktop or Claude Code with a read-only key. The assistant reads the rows you've already collected, at no extra cost on Scrapewise. With a full-access key it can start a run for you too.
- Which of my ASINs lost the Buy Box this week?
- Which competitor cut prices the most since Monday?
- Show the keywords where I dropped out of the top 10.
What you send and what you get
You send a link and a column list. Everything else — market, currency, which products are on the page — comes from the page, so there is nothing to configure twice.
- Link to a Zappos pagerequired
Open the product or category page in your browser and copy the address. Any Zappos country domain works the same way.
https://www.zappos.com/ - Your column listrequired
Field name, type and one line of plain English per column. Written once, reused on every run.
brand, product_title, article_code, colour - How often it runsoptional
Hourly, daily, weekly or on demand through the API. Daily is what most price monitoring uses.
Daily at 06:00 UTC
One row per article, 7 columns each
- product_title
- price
- currency
- availability
- brand
- sku
- source_url
REST API, CSV or Excel. The column set stays the same between runs, so downstream jobs do not re-map fields.
What a run on Zappos actually returned
This is real output, not a mock-up. 4 rows, collected on 3 October 2026 from live zappos.com product pages through our own engine, the same way one of your runs would. Prices move, so treat the numbers as a sample of shape rather than a current price list.
All 7 columns
- product_title
- price
- currency
- availability
- brand
- sku
- source_url
product_titleproduct_titleProduct title as the retailer writes it | pricepricePrice the page is charging today | currencycurrencyCurrency the page quoted | availabilityavailabilityStock state the page published | brandbrandBrand as the retailer labels it | skuskuThe retailer's own product code | source_urlsource_urlThe exact page this row was read from |
|---|---|---|---|---|---|---|
| Hikebound™ II Jacket | 90 | USD | InStock | Columbia | 9960882 | https://www.zappos.com/p/columbia-hikebound-ii-jacket-black/product/9960882/color/3 |
| Pardon My Jacket | 95.65 | USD | InStock | Columbia | 9987921 | https://www.zappos.com/p/columbia-plus-size-lillian-ridge-ii-jacket-black/product/9962282/color/3 |
| Bahama™ II Long Sleeve | 60 | USD | InStock | Columbia | 9987914 | https://www.zappos.com/p/columbia-pfg-bahama-ii-long-sleeve-metal/product/10050531/color/11422 |
| Roc Tech Cargo Pant | 54 | USD | InStock | Columbia | 10002442 | https://www.zappos.com/p/columbia-roc-cargo-pants-ancient-fossil/product/10002838/color/789016 |
Column names are ones we chose when declaring the schema for this run. Yours can be named whatever your downstream job already expects. We pointed the run at 14 Zappos product pages and 4 came back with a readable price. The rest returned something other than a product page, which is ordinary on this storefront and the reason the tier named above is what it is. We publish what we measured, not what we expect.
What a Zappos page costs
Pay-as-you-go from your wallet. No plan, no monthly fee, no seat count.
Measured on 3 October 2026, not assumed. A plain HTTP request for a zappos.com page comes back with the page, so most runs never need a browser and never need a residential exit.
500 Zappos pages checked once a day for a month is 15,000 pages.
about EUR 7.50 for the month
You are charged for what a run actually used, not what it was expected to need, and your balance never expires.
See the full price list →What this page is not promising
We would rather say this here than in a support ticket.
No dedicated Zappos endpoint
There is no Zappos API in our catalogue and no pre-built Zappos schema. The AI scraper reads the page you point it at — that is the whole mechanism, and it is why it works on pages nobody built a connector for.
Nothing behind a login
It reads what a visitor can see. Account pricing, contract pricing and anything behind a sign-in are out of scope.
No field the page does not show
If the page does not print it, the scraper cannot return it. Identifiers like EAN or GTIN only come back where the retailer publishes them.
A price is a point in time
Every row carries the timestamp of the run that collected it. A price without one is not evidence, which is why the column is in the default schema.
Zappos has one specific trap
Price can differ by size within one product, so a single product price is an approximation.
Not a bulk dump of the catalogue
You give it the URLs you care about. It does not crawl zappos.com end to end, and a schedule that tried to would cost more than the answer is worth.
Typical fields the AI scraper extracts from a Zappos page
Treat this as a starting point rather than a fixed schema. What comes back is whatever the page actually shows on the day of the run.
Markdown, not price
The interesting number is the distance between the original price and today's price, and how fast that distance is growing.
- Current price
- Original price, where the page shows one
- Markdown percentage as stated
- Campaign or sale badge wording
- Currency and market the price belongs to
Size run and availability
The column fashion teams actually ask for, and the one most price monitoring tools do not collect.
- Every size listed for the variant
- Which sizes are still available
- Which sizes are marked as few left, where the page says so
- Whether the variant is sold out entirely
- Delivery window shown for the article
Article identity
Fashion sites issue their own article code per colour variant, which is the most reliable thing on the page to key a comparison on.
- Site's article code
- Brand
- Colour variant
- Category breadcrumb
- Material and care text, where printed
- Rating and review count, where shown
- Product image URLs
The column list is one you write: name each field, give it a type and a line telling the AI what to look for. The schema belongs to your run, not to us. How Custom Schema works →
What it cannot give you If a field is not visible on the page, the scraper cannot invent it. Identifiers such as EAN or GTIN only come back when Zappos publishes them.
What people use Zappos data for
Markdown cadence tracking
When competitors start discounting, how deep they go and how fast. That is a curve you build by scraping daily, and it is invisible to a weekly check.
Size availability as a competitive signal
An article at minus fifty percent with two sizes left is clearing stock, not attacking you. The same discount with a full size run is. Most monitoring tools collect the price and miss the distinction.
Full-price sell-through estimation
Sizes disappearing from a size run at full price, read daily, is the closest public proxy for sell-through there is.
Brand protection in fashion
If you sell through partners, this is how you see what your articles are actually listed at, per market, per colour. That is the evidence a channel conversation needs.
Assortment and range research
Which brands, colours and price points a category actually carries, rather than what a trend report says it carries.
Feeding your own markdown rules
The export is a normal REST API or CSV, so it drops into whatever markdown logic you already run.
What makes Zappos harder than an ordinary storefront
Here is what the scraper is actually up against on zappos.com, measured rather than assumed.
Access
- Plain HTTP requests are answered, but the answer is the shell of the page rather than the priced version of it
- No named protection vendor on the response, which is why this one lands on a cheaper tier than most of the cohort
- robots.txt publishes sitemaps, which is the cheapest way to build the URL list a run works through
Variants are the whole problem
- Every colour variant is usually a separate URL with its own article code and its own price
- Size availability changes daily and independently of price, and it decides whether an article is really competing
- A size hidden rather than marked out of stock is simply absent from the page
- Category pages are lazily loaded and infinitely scrolled, so a category sweep is a list of URLs rather than one request
What the page publishes
- No product-level structured data is published, so every field is read off the rendered page
- Price can differ by size within one product, so a single product price is an approximation.
- Price is one of the last things the page settles on, so a read taken too early records the placeholder rather than the number
Keeping a history
- A single read is a snapshot; the value is in the series, which means the run has to be scheduled and the rows kept
- Every row carries the timestamp of the run that produced it, so two days can be compared without guesswork
- Columns stay stable between runs, so a dashboard written once does not break when the site redesigns
Zappos scraping — questions
What people ask before pointing the scraper at zappos.com.
Zappos does run a developer portal at {'url': 'https://www.zappos.com/', 'status': 200, 'signals': ['clientid', 'endpoint', 'sandbox']}. It is built for partners and sellers rather than for someone who wants to read prices, so the access you can get through it is not the access most people arrive here looking for.
Ready to pull Zappos data into your stack?
Start free — or talk to our team about your exact fields, refresh cadence and volume.